The Monolith That Ate Manhattan
Three years ago, I inherited a monolith that had grown like a digital tumor. What started as a sensible Rails application had metastasized into 400,000 lines of tightly coupled code serving everything from user authentication to payment processing to recommendation algorithms. The entire engineering team of twelve developers worked in the same repository, merging to master felt like playing Russian roulette, and our deployment pipeline took forty-seven minutes on a good day.
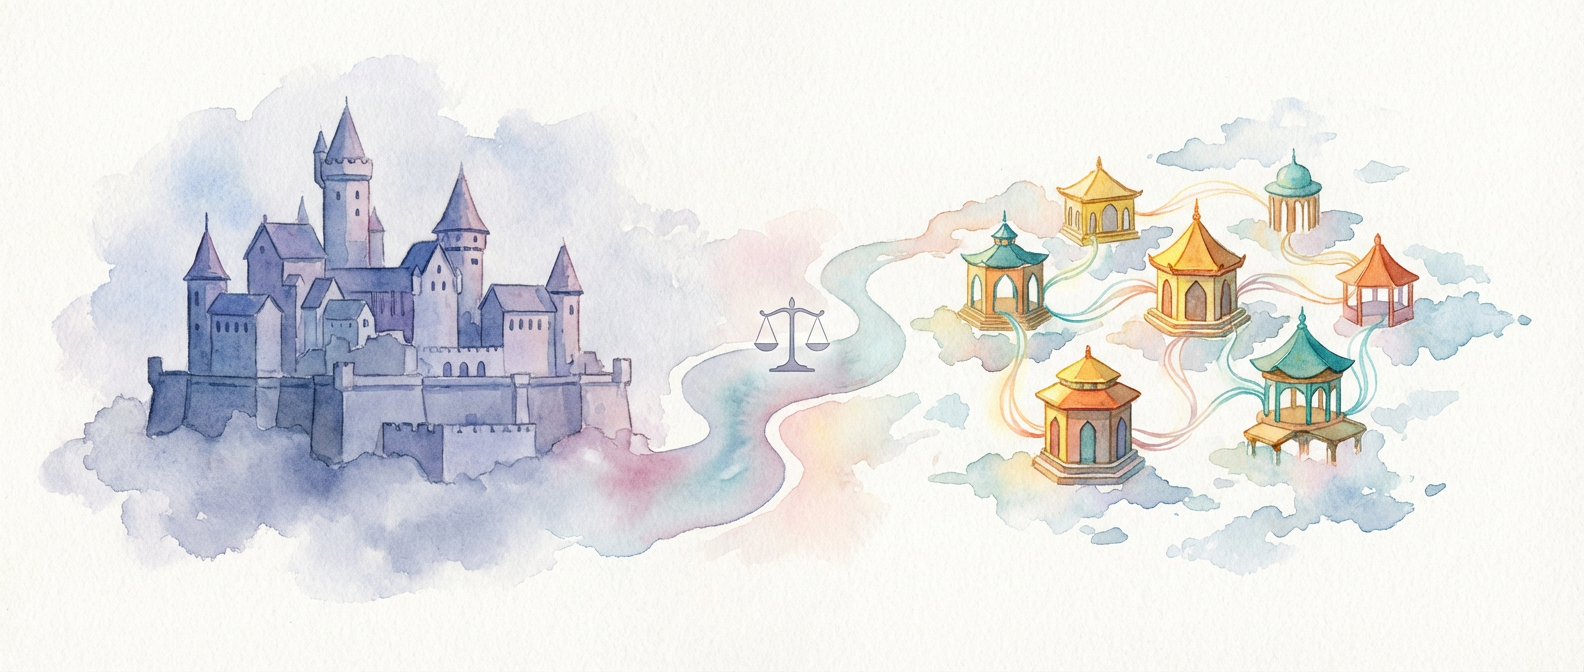
The business was scaling rapidly. We hit that classic inflection point where every new feature request triggered heated debates about architectural debt. Our CTO had attended one too many conferences and came back with microservices fever. “We need to break this thing apart,” he declared, armed with slide decks about Netflix’s success stories. I nodded politely while internally calculating the blast radius of what he was proposing.
Looking back, we were experiencing every classic monolith pain point. Database migrations required coordinating with half the team. A bug in the recommendation engine could take down checkout. Our CI/CD pipeline had become a bottleneck that made feature delivery feel like watching paint dry. Something had to give, but the question wasn’t whether to change, it was how to change without accidentally building a distributed system that would make our current problems look quaint.
The Great Unbundling
We started with what seemed like the obvious wins. The recommendation service was CPU-intensive and had different scaling requirements than the rest of the application. User management was relatively self-contained and desperately needed better caching strategies. Payment processing was already isolated behind internal APIs, making it a natural candidate for extraction.
The first service we carved out was user authentication. It felt safe. Well-defined boundaries, clear API contracts, and minimal cross-cutting concerns. The extraction took three months of careful surgery, including building a new service, migrating data, implementing proper service-to-service communication, and adding monitoring that actually told us when things were breaking. When we finally flipped the switch, nothing exploded. Success tasted like stale coffee and the relief of a deployment that didn’t wake anyone up at 3 AM.
Emboldened by our victory, we accelerated the timeline for the next extraction. This was our first mistake. The recommendation engine seemed straightforward until we realized it had tentacles reaching into user behavior tracking, A/B testing infrastructure, and real-time analytics. What looked like a three-week project turned into a six-month odyssey of discovering hidden dependencies and rebuilding integrations we didn’t know existed.
By the end of year one, we had five microservices and a newfound appreciation for the complexity we had unleashed. Our monitoring dashboard looked like a Christmas tree. Service-to-service authentication had become a part-time job for our DevOps engineer. Debugging issues now required correlation across multiple log streams. We had traded the simplicity of a single deployment for the cognitive overhead of distributed systems, and some days that felt like a Faustian bargain.
Lessons From the Trenches
The most brutal lesson came during our first major incident in the new architecture. A cascade failure started when the payment service experienced a memory leak, which caused timeouts that backed up our message queues, which triggered circuit breakers that made the checkout flow fail silently. In the monolith days, this would have been a straightforward memory investigation. In microservices land, it became a four-hour debugging session across six different services with three engineers screen-sharing and muttering increasingly creative profanity.
But we also discovered genuine advantages that the conference talks hadn’t oversold. Different teams could deploy independently without stepping on each other’s toes. We scaled the recommendation service separately from user management, optimizing resource allocation in ways that would have been impossible in the monolith. New engineers could understand and contribute to individual services without needing to understand the entire system. When done right, microservices delivered on their promise of reducing cognitive load and enabling team autonomy.
The key insight was that microservices aren’t a technical decision, they’re an organizational one. Each service boundary represents a communication interface between teams. If your organization isn’t ready for the overhead of managing those interfaces, you’re not ready for microservices. Conway’s Law isn’t just an observation. It’s a design constraint you ignore at your own peril.
The Real Trade-offs
After two years of living with both architectures, the trade-offs became crystal clear. Monoliths excel at developer productivity for small to medium teams. You can grep your way through the entire codebase, database transactions work exactly as expected, and refactoring across modules is straightforward. The operational overhead is minimal. One deployment, one database, one set of logs to check when things go sideways.
Microservices shine when you need organizational scalability and have the engineering maturity to handle distributed systems complexity. They enable parallel development, technology diversity, and independent scaling. But they require investment in tooling, monitoring, and operational practices that many teams underestimate. Service mesh configurations, distributed tracing, and eventual consistency aren’t just buzzwords. They’re essential infrastructure that someone on your team needs to understand deeply.
The dirty secret of our migration was that we could have solved most of our original problems without breaking apart the monolith. Better modularization, improved CI/CD pipelines, and database optimization would have addressed our immediate pain points. We chose microservices partly because it felt like the sophisticated, forward-thinking approach. Sometimes the boring solution is the right solution, but boring doesn’t look good in architecture review presentations.
What I’d Do Differently
If I could replay this migration, I’d start with a “modular monolith” approach. Clean up the internal architecture first, establish clear module boundaries, and prove that teams can work independently within the same codebase. Only extract services when you have evidence that the benefits outweigh the complexity costs, not when it feels like the next logical step in your architectural evolution.
I’d also invest heavily in observability before the first service extraction. Distributed tracing, centralized logging, and proper metrics collection aren’t nice-to-haves in microservices land. They’re survival tools. We learned this the hard way, retro-fitting monitoring into services that were already in production and discovering blind spots during outages rather than during planning sessions.
The most important lesson was that architecture decisions should be reversible when possible. We designed our service boundaries to be permeable, allowing us to merge services back together if the overhead wasn’t justified. Two of our original five microservices ended up getting consolidated because the operational complexity outweighed the benefits. Being wrong about service boundaries isn’t a failure. It’s data.
Every architecture decision involves trade-offs, and the best choice depends on your team, your constraints, and your specific problems. Whether you’re maintaining a monolith or managing microservices, the goal remains the same: delivering value to users without accidentally setting your infrastructure on fire. What architectural decisions have you wrestled with lately? I’d love to hear about your own war stories in the comments.