The Great Cloud Cost Theater
After fifteen years of watching companies migrate to the cloud with the enthusiasm of lottery winners, I’ve noticed something peculiar. The same organizations that meticulously track every office supply purchase suddenly develop amnesia when AWS sends them a five-figure monthly bill. They nod sagely at terms like “elasticity” and “pay-as-you-go” while their infrastructure costs grow faster than a teenager’s appetite.
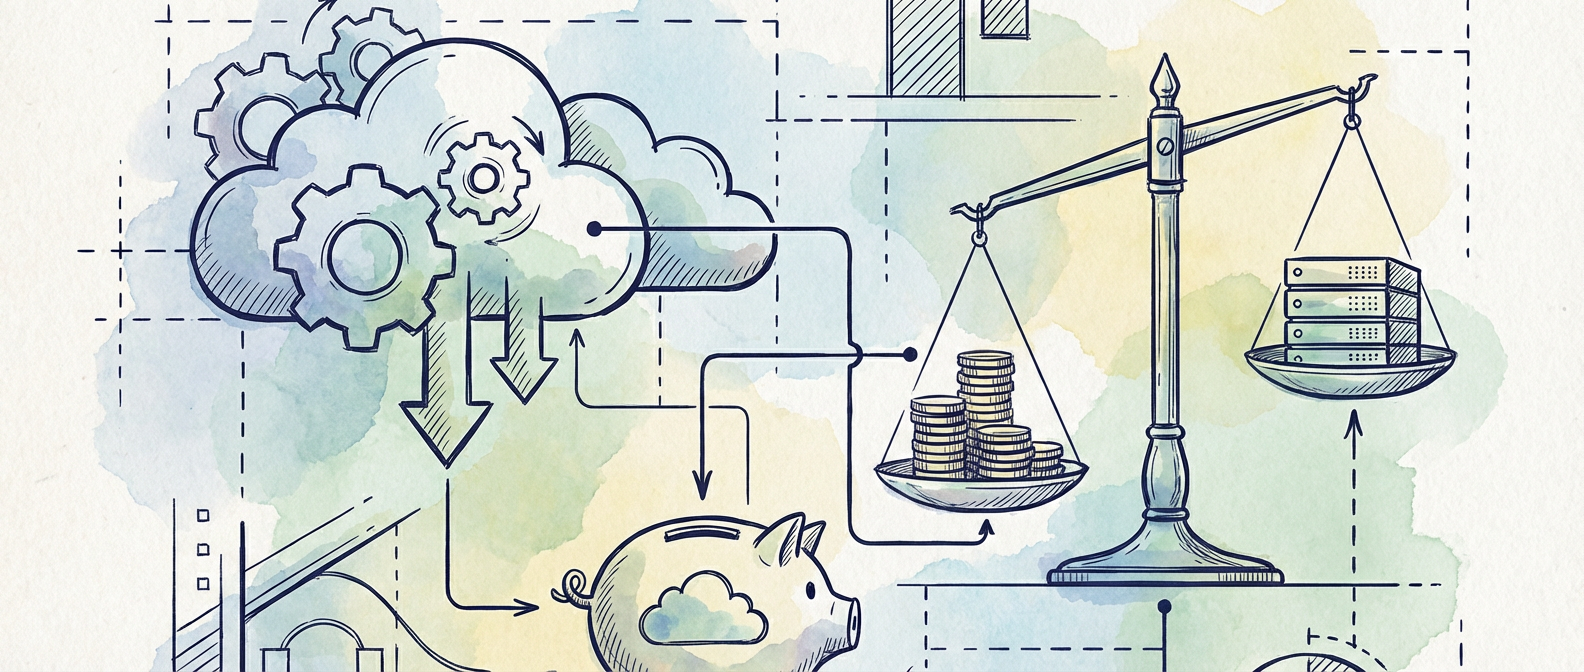
The dirty secret of cloud migration? Most companies are running the equivalent of a Ferrari in first gear. They’ve traded the predictable pain of managing physical servers for the chaotic surprise of cloud bills that arrive like uninvited relatives during the holidays. The cloud isn’t the problem here. The problem is that we’ve all agreed to pretend that throwing money at AWS is the same as understanding our infrastructure.
I’ve audited enough cloud environments to know that most optimization advice out there ranges from useless to actively harmful. Those generic blog posts telling you to “right-size your instances” are about as helpful as telling someone to “drive better” for gas mileage. Real cost optimization means getting uncomfortably close to your actual usage patterns, not following some checklist written by someone who’s never seen your workload.
The Reserved Instance Cargo Cult
Let’s start with everyone’s favorite cost optimization silver bullet: Reserved Instances. Cloud vendors have done an impressive job convincing the world that RIs are free money. Watching engineering teams debate RI strategies feels like observing a cargo cult ritual. Teams spend weeks analyzing usage patterns to lock in savings on instances they’ll inevitably need to resize in six months.
Here’s what the RI evangelists won’t tell you: Reserved Instances are basically a bet against your own ability to optimize your infrastructure. You’re paying upfront for the privilege of not improving your resource utilization. I’ve seen companies save 30% on their EC2 costs with RIs while their actual resource utilization hovers around 15%. Congratulations, you’ve optimized your way to paying 70% of full price for infrastructure you barely use.
The math gets even worse when you factor in opportunity cost. That money you’ve locked up in three-year RIs could have funded the engineering time to actually fix your resource utilization problems. But fixing problems means admitting they exist, and it’s much easier to buy your way out of inefficiency than to confront it directly.
Don’t get me wrong. RIs have their place, especially for stable, long-running workloads that you’ve already optimized. But treating them as your primary cost optimization strategy is like using duct tape as your primary construction material. It works until it doesn’t, and when it fails, it fails spectacularly.
The Autoscaling Placebo Effect
Autoscaling is another one of those features that sounds revolutionary in principle and disappointing in practice. The theory is seductive: your infrastructure automatically adapts to demand, scaling up during peak usage and scaling down during quiet periods. The reality is that most autoscaling configurations are about as responsive as a government bureaucracy.
The fundamental problem with autoscaling isn’t technical complexity, though that’s certainly part of it. The real issue is that effective autoscaling requires you to understand your application’s performance characteristics in granular detail. How long does your application take to initialize? What’s the relationship between CPU utilization and actual performance? How do you handle stateful components that can’t be easily scaled horizontally?
I’ve debugged autoscaling groups that were stuck in permanent scale-up loops because someone set the CPU threshold too low, and others that never scaled at all because the metrics they were watching had no correlation with actual system load. My personal favorite was a system that would scale up aggressively during daily batch jobs, then scale down so slowly that it was still running oversized infrastructure when the next batch job started.
The uncomfortable truth? Most applications aren’t built for effective autoscaling. Adding autoscaling to a monolithic application that takes five minutes to start and doesn’t handle graceful shutdowns is like adding a turbocharger to a car with square wheels. The theoretical performance improvements are irrelevant because the fundamental architecture can’t support them.
Monitoring: The Awkward Truth About What You’re Actually Paying For
Here’s where the conversation gets uncomfortable for most teams. Real cost optimization requires monitoring that goes way beyond the pretty dashboards your cloud provider gives you. Those built-in cost analysis tools are designed to make you feel informed while keeping you sufficiently confused about where your money is actually going.
Effective cost monitoring means tracking resource utilization at the application level, not just the infrastructure level. It means understanding the relationship between your business metrics and your cloud spending. Can you answer questions like “How much does it cost us to process one customer order?” or “What’s the marginal cost of supporting an additional 1000 users?”
The engineering teams that excel at cost optimization have built custom monitoring that tracks resource usage by feature, by team, and by business function. They can tell you exactly how much their search functionality costs to operate, or what percentage of their compute budget goes to background data processing. This level of visibility is uncomfortable because it forces you to confront the efficiency of your technical decisions in financial terms.
I’ve worked with teams that discovered they were spending more on monitoring and logging than on their actual application infrastructure. Others found that a background job that ran for thirty seconds every hour was consuming more resources than their entire web application stack. These discoveries are only possible when you measure what you’re actually using, not what you think you’re using.
The Real Cost Optimization Playbook
Genuine cost optimization starts with accepting that your intuitions about resource usage are probably wrong. The database you think is the bottleneck might be idling most of the time. The microservice you assumed was lightweight might be consuming more memory than your main application. The only way to optimize costs effectively is to measure actual usage patterns, not theoretical ones.
Start by implementing resource utilization monitoring that goes beyond basic CPU and memory metrics. Track application-specific metrics like request processing time, queue depth, and database connection pool usage. Build dashboards that correlate business metrics with infrastructure costs. Make cost visibility part of your regular operational review process.
Then, and only then, start optimizing. Right-size instances based on actual usage patterns, not vendor recommendations. Implement autoscaling with aggressive scale-down policies and proper health checks. Use spot instances for workloads that can handle interruption. Consider serverless architectures for truly variable workloads.
The most effective cost optimization I’ve seen didn’t come from fancy tools or vendor consulting sessions. It came from engineering teams that treated infrastructure efficiency as a core engineering discipline, with the same rigor they applied to application performance and security. They measured everything, questioned every assumption, and weren’t afraid to redesign systems that couldn’t be optimized incrementally.
What’s your experience been with cloud cost optimization? Have you discovered any particularly surprising resource usage patterns in your own infrastructure? I’d be curious to hear about the optimization wins (or failures) that didn’t make it into the vendor case studies.